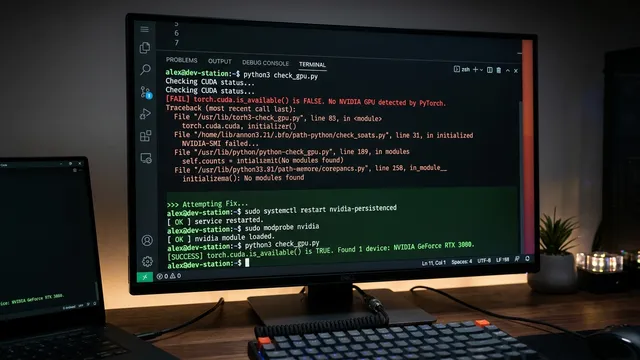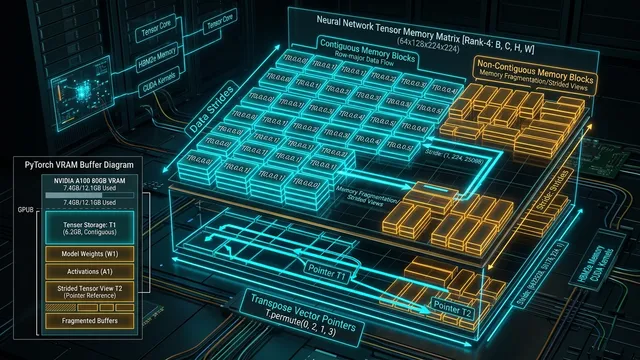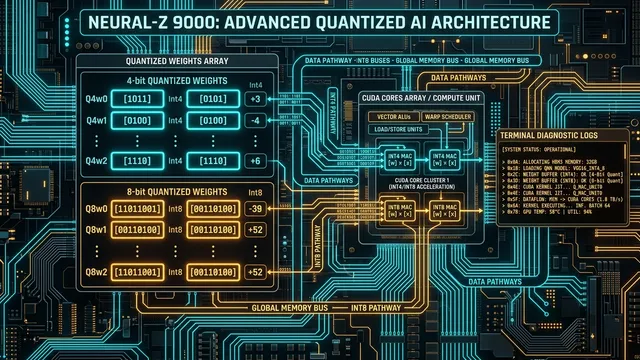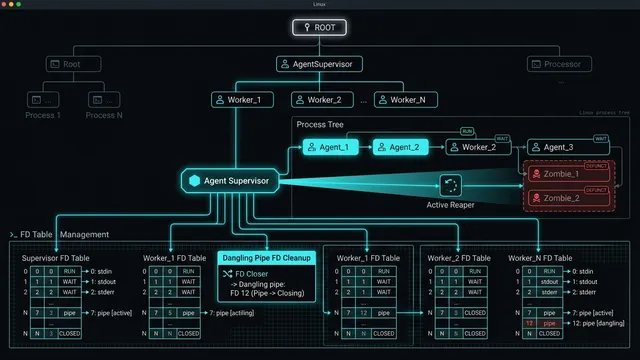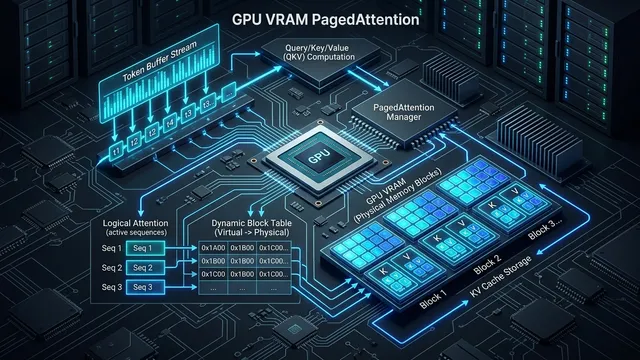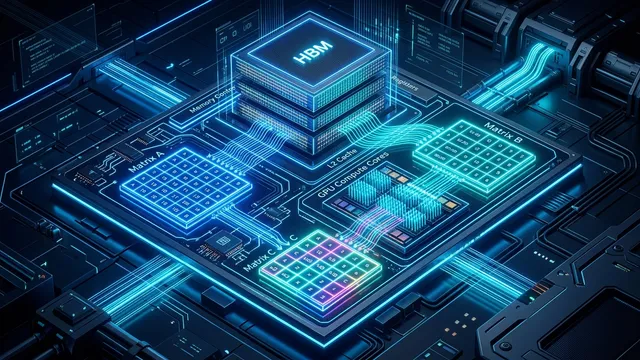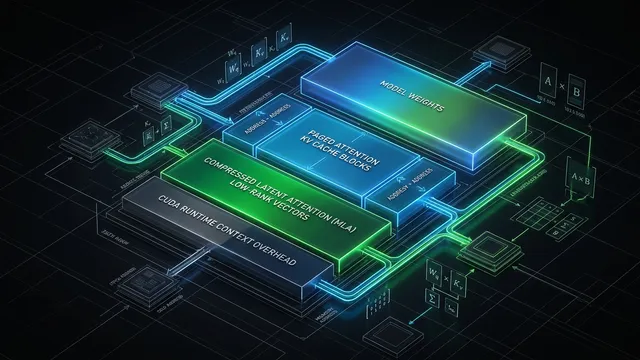
LLM VRAM & KV Cache Sizing Guide: Exact Memory Formulas for GQA, MLA, and Quantization on Linux
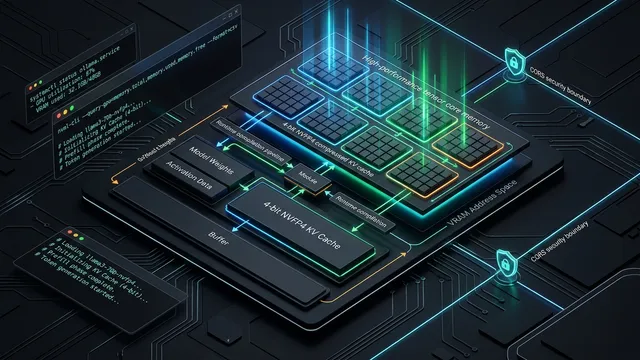
Calculate exact GPU VRAM for local LLMs on Linux. Covers GQA vs DeepSeek MLA KV cache equations, AWQ group-scale overhead, and a Python sizing CLI.
Read Technical Guide →