How to Fix 'RuntimeError: Watchdog caught collective operation timeout' in PyTorch NCCL on Linux
To resolve RuntimeError: Watchdog caught collective operation timeout: WorkNCCL(OpType=ALLREDUCE) in PyTorch on Linux, enable asynchronous error handling and identify which GPU rank stalled behind the synchronization barrier:
That stalls the pipeline. Execution halts immediately.
# 1. Export diagnostic and network interface variables in your shell
export TORCH_NCCL_ASYNC_ERROR_HANDLING=1
export TORCH_NCCL_DUMP_ON_TIMEOUT=1
export NCCL_DEBUG=INFO
export NCCL_DEBUG_SUBSYS=COLL,P2P
export NCCL_SOCKET_IFNAME=eth0,eno1,ens3

# 2. Increase the process group timeout in your Python training or serving script
import datetime
import torch.distributed as dist
# Extend collective timeout from 10 minutes to 30 minutes
dist.init_process_group(
backend="nccl",
init_method="env://",
timeout=datetime.timedelta(minutes=30)
)Why the Watchdog Timeout Triggers
PyTorch distributed runtime launches a dedicated background watchdog thread when you initialize the NCCL backend. This thread tracks every collective communication call (AllReduce, AllGather, ReduceScatter, and Broadcast).
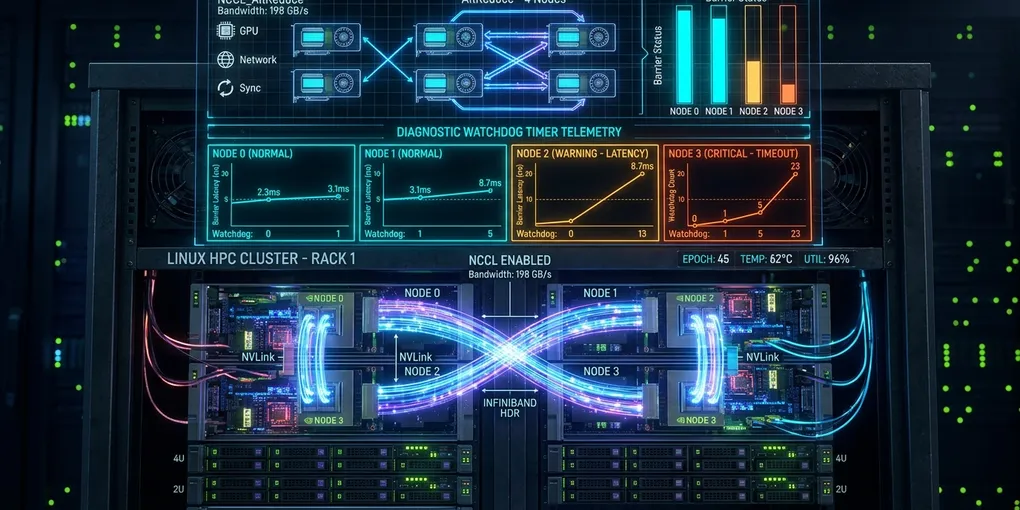
When rank 0 initiates an AllReduce operation, all participating GPUs across nodes or sockets must enter the same collective barrier. If one GPU (a “straggler”) is delayed by CPU data loading bottlenecks, dynamic shape kernel compilation, or a network interface drop, the remaining GPUs remain stalled waiting for incoming tensors. When the elapsed duration exceeds the configured process group timeout, the watchdog thread terminates the entire distributed process with WorkNCCL(OpType=ALLREDUCE) timeout.
+------------------------------------------------------------------------------------+
|               NCCL COLLECTIVE BARRIER DESYNCHRONIZATION TRACE                      |
+------------------------------------------------------------------------------------+
| GPU Rank 0: Enters AllReduce Barrier [READY] ------------------+                   |
| GPU Rank 1: Enters AllReduce Barrier [READY] ------------------|                   |
| GPU Rank 2: Enters AllReduce Barrier [READY] ------------------|                   |
| GPU Rank 3: Blocked on CPU DataLoader / JIT compile [STALLED]  |                   |
+----------------------------------------------------------------|-------------------+
                                                                 |
                                                                 v
                                         [Wait timer reaches 1800 seconds]
                                                                 |
                                                                 v
+------------------------------------------------------------------------------------+
| PyTorch Watchdog Thread: Triggers SIGABRT / Process Group Tear-down                |
| RuntimeError: Watchdog caught collective operation timeout: WorkNCCL(OpType=...)   |
+------------------------------------------------------------------------------------+
Root Cause Diagnostic Matrix
The following table categorizes the four primary root causes of NCCL watchdog timeouts across multi-GPU Linux systems.
| Root Cause | Visible Symptom in Logs | Primary Trigger | Direct Solution |
|---|---|---|---|
| Worker Desynchronization | Crash occurs after 10 to 30 minutes on random steps | Slow disk I/O, heavy CPU image augmentations, unbalanced datasets | Pin DataLoader memory, increase num_workers, use persistent_workers=True |
| Network Interface Shadowing | Timeout occurs immediately on the first collective call | NCCL binds to virtual Docker bridge (docker0, virbr0, tailscale0) |
Set NCCL_SOCKET_IFNAME=eth0,ens3 to force physical NIC binding |
| JIT Compilation Delay | Crash occurs on the very first forward step (torch.compile) |
Rank 0 compiles Triton/Inductor kernels while other ranks wait idle | Run an explicit forward warmup step or increase timeout during init |
| PCIe P2P Deadlock | Crash occurs during high-bandwidth tensor transfer | Peer-to-Peer DMA stalls across non-NVLink PCIe switches | Set NCCL_P2P_DISABLE=1 or NCCL_IB_DISABLE=1 |
Step-by-Step Resolution Protocols
Step 1: Pinpoint the Stalled Rank with NCCL Flight Recorder
By default, PyTorch prints the stack trace of the ranks that timed out, which are usually the healthy ranks waiting at the barrier, not the straggler that caused the delay.
Enable the NCCL Flight Recorder dump to force PyTorch to print the exact file, line number, and operation of the stalled rank:
# Export in your launch script before invoking torchrun
export TORCH_NCCL_DUMP_ON_TIMEOUT=1
export TORCH_NCCL_TRACE_BUFFER_SIZE=2000
export TORCH_DISTRIBUTED_DEBUG=DETAIL
When a timeout occurs, inspect the generated trace dump. Look for the rank that shows Status: IN_PROGRESS on a non-communication CPU operation while other ranks report Status: WAITING_AT_BARRIER.
Step 2: Fix Network Interface Shadowing in Docker and Multi-Node
In containerized environments (Kubernetes, Docker, Slurm), Linux creates multiple virtual network interfaces. NCCL scans available network adapters and frequently binds to an internal loopback or bridge interface that cannot route cross-host traffic.
Inspect your active network adapters on Linux:
# List available network interfaces
ip -o link show | awk -F': ' '{print $2}'
If you see eth0 or eno1 alongside docker0 or flannel.1, tell NCCL explicitly which interface to use:
# Specify the correct physical network interface
export NCCL_SOCKET_IFNAME=eth0,eno1,ens3f0

# If running over RoCE or InfiniBand, specify the HCA port
export NCCL_IB_HCA=mlx5_0,mlx5_1
Step 3: Prevent torch.compile JIT Desynchronization
When using torch.compile(mode="reduce-overhead"), PyTorch traces the model and generates optimized CUDA kernels during the first forward step. If one rank finishes compilation earlier than another rank (due to uneven CPU core load), subsequent ranks enter the collective communication layer while the straggler is still compiling C++ source files.
Resolve this by inserting a synchronization barrier before compilation and extending the initialization timeout:
import datetime
import torch
import torch.distributed as dist

def setup_distributed_model(model):
    # Initialize with a generous timeout to allow first-run compilation
    dist.init_process_group(
        backend="nccl",
        timeout=datetime.timedelta(minutes=45)
    )

    local_rank = dist.get_rank()
    torch.cuda.set_device(local_rank)

    # Synchronize all GPUs before invoking torch.compile
    dist.barrier()

    compiled_model = torch.compile(model)
    return compiled_model
Step 4: Eliminate DataLoader CPU Bottlenecks
A frequent cause of random watchdog timeouts during training epochs is Python garbage collection or blocking disk reads inside worker processes.
Ensure your PyTorch DataLoader isolates I/O and uses shared memory correctly on Linux:
from torch.utils.data import DataLoader

train_loader = DataLoader(
    dataset=train_dataset,
    batch_size=32,
    shuffle=False,  # Use DistributedSampler instead
    sampler=torch.utils.data.distributed.DistributedSampler(train_dataset),
    num_workers=4,
    pin_memory=True,          # Pin pages directly into GPU-accessible staging memory
    persistent_workers=True,  # Keep worker processes alive across epoch transitions
    prefetch_factor=2         # Preload batches to avoid stalling the collective barrier
)
Verification Test Script
Run this multi-process script using torchrun on your Linux workstation to verify that collective operations, timeouts, and heartbeat watchdog monitoring function without deadlock:
# test_nccl_watchdog.py
import datetime
import os
import torch
import torch.distributed as dist

def run_test():
    local_rank = int(os.environ.get("LOCAL_RANK", 0))
    torch.cuda.set_device(local_rank)

    # Initialize process group with explicit watchdog timeout
    dist.init_process_group(
        backend="nccl",
        init_method="env://",
        timeout=datetime.timedelta(seconds=60)
    )

    rank = dist.get_rank()
    world_size = dist.get_world_size()

    print(f"[Rank {rank}/{world_size}] Process group established on GPU: {torch.cuda.get_device_name(local_rank)}")

    # Allocate test tensor on GPU
    tensor = torch.ones(1024, 1024, device=f"cuda:{local_rank}", dtype=torch.float32) * (rank + 1)

    # Execute collective AllReduce
    dist.all_reduce(tensor, op=dist.ReduceOp.SUM)
    torch.cuda.synchronize()

    expected_sum = sum(range(1, world_size + 1))
    assert tensor[0, 0].item() == expected_sum, f"Reduction mismatch on rank {rank}"

    dist.barrier()
    if rank == 0:
        print(f"[SUCCESS] AllReduce across {world_size} GPUs completed without watchdog timeout.")

    dist.destroy_process_group()

if __name__ == "__main__":
    run_test()
Launch the test script across all available GPUs:
torchrun --nproc_per_node=2 test_nccl_watchdog.pyIf the command prints [SUCCESS] AllReduce across 2 GPUs completed without watchdog timeout, your NCCL configuration and distributed communication pipelines are operating normally.
Distributed training halts immediately. Deadlocks waste GPU hours.
Official Documentation & Primary References
- PyTorch Official CUDA Semantics Documentation: Memory management, device ordinals, asynchronous execution, and stream synchronization.
- PyTorch Autograd Mechanics: Computational graph lifecycle, in-place operation checks, and backward pass execution.
- PyTorch Distributed (c10d / DDP) Documentation: NCCL backend initialization, watchdog timeouts, and gradient reduction hooks.
- NVIDIA CUDA Toolkit & Driver Documentation: Official compute capability tables, cuBLAS/cuDNN status codes, and NVML driver management.