Agentic Pulse
Practical engineering guides, GPU memory debugging, and architectural comparisons for local LLM serving (vLLM, Ollama, SGLang), Model Context Protocol (MCP), and PyTorch on Linux.
LLM Serving & Hardware
vLLM, Ollama, SGLang, AWQ/FP8 quantization, KV-cache sizing, and speculative decoding on Linux GPUs.
Browse Guides →MCP & Agent Engineering
Custom Python FastMCP servers, sqlite-vec memory, Playwright bridges, Bubblewrap sandboxes, and security.
Browse Guides →PyTorch & CUDA Debugging
Fixes for CUDA out-of-memory, FlashAttention ABI mismatches, Docker GPU passthrough, DDP, and autograd.
Browse Guides →Architecture & Comparisons
In-depth specification and architectural comparisons of open-source coding agents, vector databases, and AI gateways.
Browse Guides →Featured Core Guides
Browse all 75 guides →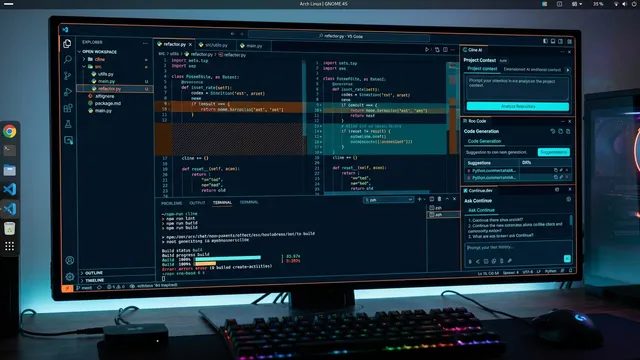
Cline vs Roo Code vs Continue: Open-Source AI Coding Extensions Compared (2026)
Architectural comparison of Cline, Roo Code, and Continue.dev in VS Code on Linux. Compare custom modes, MCP tool execution, token control, and local vLLM setup.
SearXNG vs Tavily vs Brave Search: Web Retrieval Architecture & Setup Guide for AI Agents
Architect web retrieval for AI agents on Linux. Compare self-hosted SearXNG with Tavily and Brave Search APIs across network hops, token costs, and rate limits.
Ollama vs vLLM: Local LLM Serving Architecture, Memory Management & Concurrency Guide (2026)
Compare Ollama and vLLM on Linux. Understand llama.cpp vs PagedAttention memory allocation, concurrent agent scaling, VRAM traps, and production systemd setup.
How to Fix FlashAttention-2 Installation and CUDA Kernel Mismatch Errors in PyTorch on Linux
Fix FlashAttention-2 installation failures and CUDA kernel mismatches on Linux. Resolve Ninja compiler OOM, ABI discrepancies, and wheel compatibility.
How to Sandbox AI Coding Agents with Bubblewrap (bwrap) on Linux
Isolate autonomous AI coding agent bash executions using unprivileged Bubblewrap sandboxes. Restrict filesystem access and block lateral network movement.
How to Run Qwen 3.8 27B Locally on Linux with vLLM: Hybrid Attention, Reasoning Parsers, and AWQ/FP8 Setup
Step-by-step guide to serving Qwen 3.8 27B on Linux using vLLM. Configure Delta Net hybrid attention, reasoning parsers, 4-bit AWQ on 24GB GPUs, and FP8 setups.
Recent Publications
View full archive →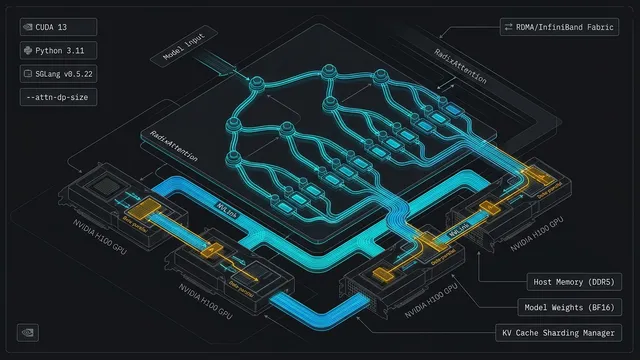
SGLang v0.5.22 Linux Migration Guide: Fixing Python 3.11, CUDA 13, and DP Attention Breaking Changes
Fix SGLang v0.5.20 to v0.5.22 upgrade failures on Linux. Covers the silent Python 3.10 pip pin, CUDA 12 retirement, and --attn-dp-size CLI flag changes.
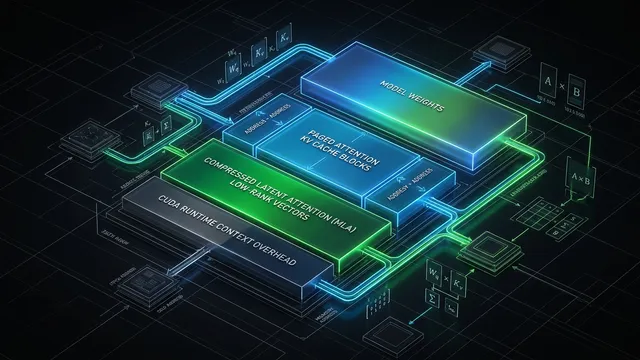
LLM VRAM & KV Cache Sizing Guide: Exact Memory Formulas for GQA, MLA, and Quantization on Linux
Calculate exact GPU VRAM for local LLMs on Linux. Covers GQA vs DeepSeek MLA KV cache equations, AWQ group-scale overhead, and a Python sizing CLI.
LiteLLM Supply Chain Incident Response: Removing the cook.pth Backdoor and Hardening AI Gateways on Linux
Resolve the LiteLLM v1.107.0 supply chain incident on Linux: detect cook.pth backdoors, safely purge infected venvs, and lock down AI proxies.
PyTorch 2.15 Upgrade Guide: Python 3.11 Migration, CUDA Architecture Drops, and Linux Autograd Fixes
Troubleshoot PyTorch 2.15 breaking changes on Linux: fix Python 3.10 wheel deprecation, resolve no kernel image available on Volta, and repair autograd hooks.
vLLM v0.32 Upgrade Guide: Python 3.11 Migration, CORS Lockdown & NVFP4 KV Cache on Linux
Troubleshoot vLLM v0.32 breaking changes on Linux: fix Python 3.10 deprecation, CORS origin blocking in WebUIs, and configure NVFP4 low-precision KV cache.
vLLM v0.31 Upgrade Guide: Fast Engine Restarts with 'vllm preload', CUDA IPC Zero-Copy, and Breaking Context Changes
Master vLLM v0.31.0 on Linux. Cut engine restart latency from minutes to seconds with vllm preload and --load-format ipc_cache, and fix breaking context changes.