How to Fix SQLite Database Locked Errors in High-Throughput MCP Memory Servers on Linux
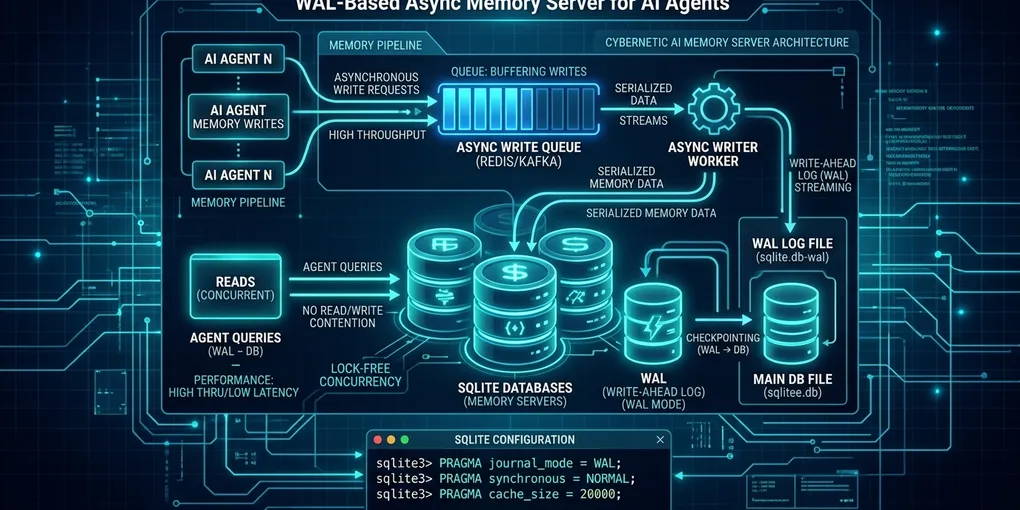
The Direct Solution: WAL Mode and Single-Writer Async Queue
That stalls the pipeline. Execution halts immediately.
To eliminate sqlite3.OperationalError: database is locked in multi-agent Model Context Protocol (MCP) memory servers, switch SQLite to Write-Ahead Logging (PRAGMA journal_mode = WAL;) and route all write operations through a dedicated background task. While WAL mode permits unlimited concurrent readers alongside a writer, SQLite permits only one write transaction at any microsecond; multiple concurrent agent write calls will crash the server unless writes are serialized.
Apply these production PRAGMA settings upon every database connection initialization:
-- Execute immediately on connection open
PRAGMA journal_mode = WAL;
PRAGMA synchronous = NORMAL;
PRAGMA busy_timeout = 5000;
PRAGMA temp_store = MEMORY;
PRAGMA mmap_size = 30000000000;
PRAGMA cache_size = -64000;
Here is the complete FastMCP memory server implementation using an in-memory asynchronous write queue and non-blocking reader pool:
import asyncio
import aiosqlite
from mcp.server.fastmcp import FastMCP
from typing import Any, Dict

mcp = FastMCP("sqlite-agent-memory")
DB_PATH = "/var/lib/mcp/agent_memory.db"
write_queue: asyncio.Queue = asyncio.Queue()

async def init_db():
    async with aiosqlite.connect(DB_PATH) as db:
        await db.execute("PRAGMA journal_mode = WAL;")
        await db.execute("PRAGMA synchronous = NORMAL;")
        await db.execute("PRAGMA busy_timeout = 5000;")
        await db.execute("""
            CREATE TABLE IF NOT EXISTS agent_episodes (
                id INTEGER PRIMARY KEY AUTOINCREMENT,
                agent_id TEXT NOT NULL,
                session_key TEXT NOT NULL,
                observation TEXT NOT NULL,
                timestamp DATETIME DEFAULT CURRENT_TIMESTAMP
            )
        """)
        await db.commit()

async def write_worker():
    # Single persistent background writer that eliminates lock collisions.
    async with aiosqlite.connect(DB_PATH) as db:
        await db.execute("PRAGMA journal_mode = WAL;")
        await db.execute("PRAGMA synchronous = NORMAL;")
        await db.execute("PRAGMA busy_timeout = 5000;")
        while True:
            item = await write_queue.get()
            agent_id, session_key, observation, future = item
            try:
                await db.execute(
                    "INSERT INTO agent_episodes (agent_id, session_key, observation) VALUES (?, ?, ?)",
                    (agent_id, session_key, observation)
                )
                await db.commit()
                future.set_result(True)
            except Exception as e:
                future.set_exception(e)
            finally:
                write_queue.task_done()

@mcp.tool()
async def store_agent_memory(agent_id: str, session_key: str, observation: str) -> Dict[str, Any]:
    # Appends an episodic observation to SQLite memory without lock contention.
    loop = asyncio.get_running_loop()
    future = loop.create_future()
    await write_queue.put((agent_id, session_key, observation, future))
    await future
    return {"status": "success", "agent_id": agent_id}

@mcp.tool()
async def query_agent_memories(agent_id: str, limit: int = 10) -> list:
    # Reads agent memories concurrently using non-blocking WAL reader connections.
    async with aiosqlite.connect(DB_PATH) as db:
        await db.execute("PRAGMA busy_timeout = 5000;")
        async with db.execute(
            "SELECT session_key, observation, timestamp FROM agent_episodes WHERE agent_id = ? ORDER BY id DESC LIMIT ?",
            (agent_id, limit)
        ) as cursor:
            rows = await cursor.fetchall()
            return [{"session_key": r[0], "observation": r[1], "timestamp": r[2]} for r in rows]

if __name__ == "__main__":
    asyncio.run(init_db())
    asyncio.create_task(write_worker())
    mcp.run(transport="sse")
Why Default SQLite Settings Crash Multi-Agent Swarms
Standard SQLite operates in rollback journal mode (DELETE or TRUNCATE), which locks the entire database file for both reads and writes during any modification.
When 20 to 50 agent subtasks execute parallel research or coding jobs:
- Lock Escalation Latency: In rollback journal mode, writing requires acquiring an
EXCLUSIVElock. If an agent tool is currently running a query, the write transaction fails immediately withdatabase is lockedunless an expensive retry loop is constructed. - Missing
busy_timeout: By default, SQLite has abusy_timeoutof 0 milliseconds. If a lock is held for even 2 microseconds by another thread, the call raisesOperationalErrorinstead of waiting. - Synchronous Disk I/O: The default
synchronous = FULLtriggers two disk flushes (fsync) per commit. On standard Linux cloud disks, this limits transaction throughput to 70-120 commits per second, creating a massive backlog in agent execution queues.
Step 1: Optimize SQLite PRAGMA Directives on Linux
To configure maximum stability on Linux NVMe systems, apply these parameters in order:
1. journal_mode = WAL
Enables concurrent readers to query the database while a writer appends to the -wal file. Readers do not block writers, and writers do not block readers.
2. synchronous = NORMAL
In WAL mode, synchronous = NORMAL syncs the WAL file only at checkpoints, guaranteeing database integrity against application crashes while eliminating per-commit fsync stalls.
3. busy_timeout = 5000
Instructs SQLite to wait up to 5,000 milliseconds (retrying internally with exponential backoff) before throwing a busy error. This absorbs microsecond transaction spikes without user-visible errors.
4. temp_store = MEMORY and cache_size = -64000
Stores temporary tables and indices in RAM, and allocates 64MB of memory cache per connection (-64000 represents 64,000 KiB), eliminating disk reads for recent memory queries.
Step 2: Prevent Unbounded WAL File Growth with Active Checkpointing
If writes arrive constantly, SQLite may fail to execute its automatic 1,000-page checkpoint, causing the -wal file to swell to several gigabytes and degrading read query performance.
Add a periodic passive checkpoint task to your MCP server startup:
async def periodic_wal_checkpoint(interval_seconds: int = 300):
    # Executes non-blocking passive checkpoints to keep the WAL file under 10MB.
    while True:
        await asyncio.sleep(interval_seconds)
        try:
            async with aiosqlite.connect(DB_PATH) as db:
                # PASSIVE checkpoint transfers pages without blocking active readers or writers
                await db.execute("PRAGMA wal_checkpoint(PASSIVE);")
        except Exception as err:
            print(f"Checkpoint error: {err}")
Architectural Comparison: SQLite Concurrency Modes
Comparing locking semantics and failure behavior across SQLite journal and queueing configurations under concurrent multi-agent access:
| Database Architecture | Read/Write Concurrency | Lock Contention Behavior | Failure Mode Under Burst Writes | WAL Growth Control |
|---|---|---|---|---|
Default Rollback Journal (DELETE) |
Exclusive lock blocks readers during writes | Fails immediately on concurrent writes | Frequent OperationalError: database is locked |
N/A (Rollback journal deleted per commit) |
Standard WAL (busy_timeout=0) |
Concurrent reads with single writer | Writer contention fails without retry window | Sporadic lock errors when two tools write simultaneously | Unbounded if readers hold open snapshots |
Tuned WAL (busy_timeout=5000) |
Concurrent reads + 5s kernel retry wait | SQLite retries lock acquisition internally | Fails only if a single transaction exceeds 5 seconds | Standard 1,000-page auto-checkpoint |
| WAL + Dedicated Async Write Queue | Concurrent reads + serialized single writer | Zero write lock contention at the SQLite layer | Deterministic FIFO execution without lock errors | Bounded via periodic wal_checkpoint(PASSIVE) |
Decoupling write execution into an asyncio.Queue while serving reads from WAL shared-memory pages eliminates writer lock contention across concurrent MCP tool invocations.
Summary Verification Checklist
Before deploying your MCP memory server to production, verify your SQLite setup from the command line:
# Check current journal mode
sqlite3 /var/lib/mcp/agent_memory.db "PRAGMA journal_mode;"
# Output must be: wal

# Verify active WAL and SHM files exist
ls -lh /var/lib/mcp/agent_memory.db*
# Output must show: agent_memory.db, agent_memory.db-shm, agent_memory.db-wal
Applying WAL mode and serializing write transactions guarantees that agent swarms can scale indefinitely on a single Linux host without database deadlocks.
Official Documentation & Primary References
- Model Context Protocol (MCP) Official Specification: Protocol transport standards, stdio lifecycle management, and timeout handling.
- FastMCP GitHub Repository: Python server implementation, async event loop integration, and tool execution internals.
- Python asyncio Official Documentation: Event loop scheduling, subprocess management, and coroutine cancellation semantics.
- LangGraph Official Documentation: State graph execution, recursion limits, and conditional edge routing.