AI Coding Agent Says Tests Passed? What MCP Logs Actually Prove (2026)
A real Codex and MCP audit shows why test logs can go stale after code or pytest configuration changes, and how to verify the final revision.
Read Technical Guide →Verified AI announcements, model releases, industry developments, and practical engineering guides for AI builders.
A real Codex and MCP audit shows why test logs can go stale after code or pytest configuration changes, and how to verify the final revision.
Read Technical Guide →Anthropic launched its IPO roadshow on Nov. 10, 2026. Read the SEC-backed share counts, proposed price range, ticker and the conditions that remain unresolved.
Read News Analysis →Anthropic launched Fable and Mythos 5.2 on November 9, 2026. Understand public and restricted access, API pricing, retention rules, and tool-calling changes.
Read News Analysis →Google released Gemini 4 Carbon on Nov. 10. Here is what its API rollout, introductory prices, 1M context window and MKA benchmark actually establish.
Read News Analysis →OpenAI described Control Room on November 9, 2026. Understand job IDs, inference-layer authorization, fail-closed design, and the limits of the 35-second claim.
Read News Analysis →
Correct SGLang v0.5.22 migration advice for Python 3.11, CUDA 13 driver requirements, and deprecated DP-attention flags.
Read Technical Guide →
Calculate exact GPU VRAM for local LLMs on Linux. Covers GQA vs DeepSeek MLA KV cache equations, AWQ group-scale overhead, and a Python sizing CLI.
Read Technical Guide →
Resolve the LiteLLM v1.107.0 supply chain incident on Linux: detect cook.pth backdoors, safely purge infected venvs, and lock down AI proxies.
Read Technical Guide →
Correct PyTorch 2.15 Linux migration guidance for Python 3.11+, CUDA 13.2 wheels, older GPU architectures, and selective activation checkpointing.
Read Technical Guide →
Troubleshoot vLLM v0.32 breaking changes on Linux: fix Python 3.10 deprecation, CORS origin blocking in WebUIs, and configure NVFP4 low-precision KV cache.
Read Technical Guide →
Master vLLM v0.31.0 on Linux. Cut engine restart latency from minutes to seconds with vllm preload and --load-format ipc_cache, and fix breaking context changes.
Read Technical Guide →
Step-by-step guide to deploying the official GitHub MCP server on Linux. Configure fine-grained tokens, Docker stdio bridges, and read-only guardrails.
Read Technical Guide →
Fix PyTorch RuntimeError: element 0 of tensors does not require grad on Linux. Repair broken autograd graphs, unfreeze layers, and remove no_grad blocks.
Read Technical Guide →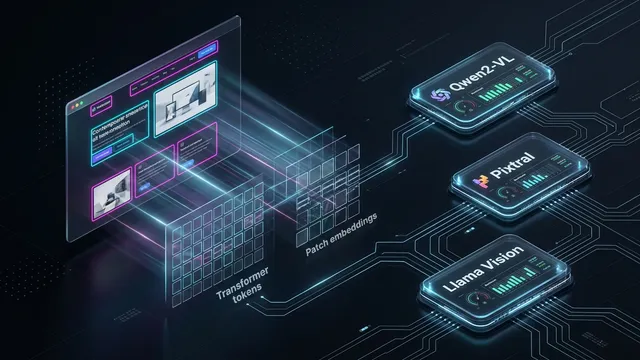
Architectural comparison of Qwen2-VL 7B, Pixtral 12B, and Llama 3.2 11B Vision on Linux: image patch tokenization, VRAM math, GUI grounding, and vLLM deployment.
Read Technical Guide →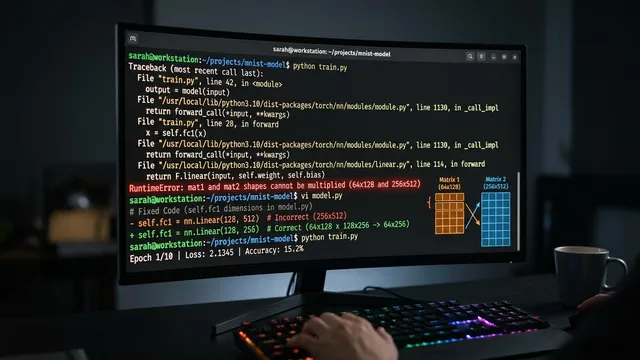
Resolve PyTorch RuntimeError: mat1 and mat2 shapes cannot be multiplied on Linux. Fix nn.Linear in_features mismatches, dynamic batch flattening, and attention head dimensions.
Read Technical Guide →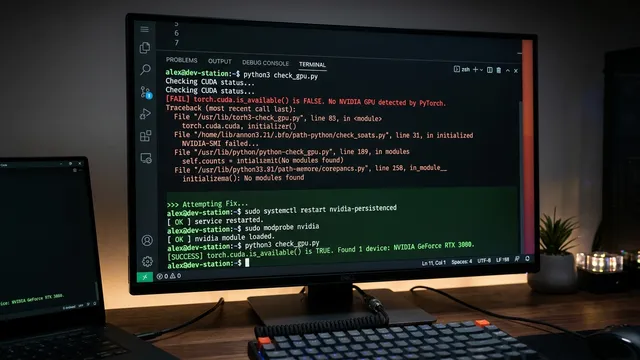
Fix torch.cuda.is_available() returning False on Linux when nvidia-smi works. Resolve CPU-only PyTorch wheels, NVIDIA driver version mismatches, and Docker GPU pass-through.
Read Technical Guide →
Fix PyTorch 'Ninja is required to load C++ extensions' on Linux. Install build dependencies, set MAX_JOBS to prevent OOM, and resolve NVCC mismatches.
Read Technical Guide →
Fix PyTorch 'Trying to backward through the graph a second time' error on Linux. Understand autograd graph buffer freeing, loss accumulation, and retain_graph traps.
Read Technical Guide →
Resolve PyTorch 'view size is not compatible with input tensor size and stride' on Linux. Understand tensor contiguity, reshape vs view, and memory overhead.
Read Technical Guide →
Resolve bitsandbytes 'CUDA Setup failed despite GPU being available' on Linux. Configure LD_LIBRARY_PATH, fix libcuda symlinks, and install CUDA 12 binaries.
Read Technical Guide →
Architectural comparison of E2B, Modal, and Daytona for AI agent code execution: Firecracker microVMs, gVisor containers, isolation boundaries, and cloud pricing.
Read Technical Guide →
Resolve PyTorch DDP expected to have finished reduction error on Linux. Fix unused model parameters, gradient checkpointing, and configure static graphs.
Read Technical Guide →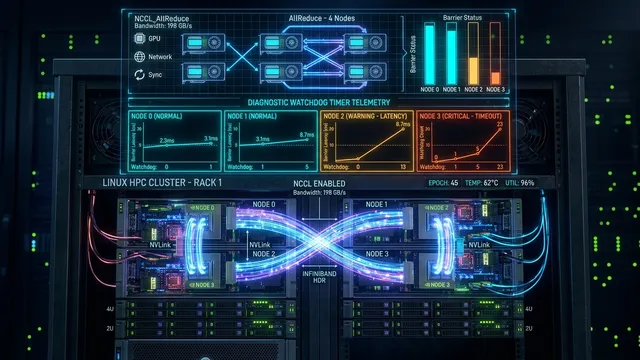
Resolve PyTorch NCCL collective operation timeout errors on Linux. Fix straggler ranks, network interface mismatches, CUDA graph desync, and socket timeouts.
Read Technical Guide →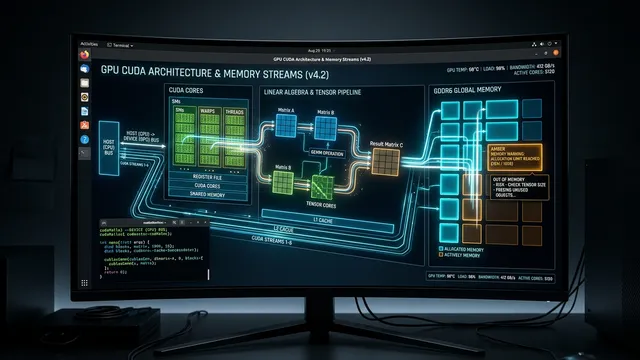
Resolve PyTorch CUBLAS_STATUS_ALLOC_FAILED crashes on Linux. Fix hidden VRAM exhaustion, PyTorch allocator fragmentation, and Docker shared memory limits.
Read Technical Guide →
Resolve PyTorch 'no kernel image is available for execution on the device' on Linux. Fix TORCH_CUDA_ARCH_LIST mismatches, driver incompatibilities, and wheel builds.
Read Technical Guide →
Resolve vLLM and PyTorch bfloat16 errors on NVIDIA T4, RTX 2080 Ti, and V100 GPUs. Cast models to float16, configure xformers, and prevent runtime crashes.
Read Technical Guide →
Architectural comparison of LiteLLM Proxy, Portkey AI Gateway, and OpenRouter: self-hosted routing, failover mechanics, virtual key budgets, and local vLLM support.
Read Technical Guide →
Reproduce and fix PyTorch's in-place autograd version-counter mismatch on CPU; distinguish it from detached tensors and missing grad_fn errors.
Read Technical Guide →
Fix local LLM function calling errors, broken JSON schemas, and empty tool_calls in vLLM, Ollama, and LiteLLM on Linux. Configure parser templates and guided decoding.
Read Technical Guide →
Fix PyTorch CUDA error: invalid device ordinal on Linux. Understand CUDA_VISIBLE_DEVICES virtual indexing, Docker GPU isolation, and multi-GPU distributed rank mapping.
Read Technical Guide →
Fix LangGraph GraphRecursionError: Recursion limit of 25 reached without hitting a stop condition on Linux. Tune recursion_limit, debug conditional routing, and add safety gates.
Read Technical Guide →
Fix PyTorch torchrun RuntimeError: Address already in use and c10d TCPStore port 29500 collision on Linux. Kill zombie workers and allocate dynamic master ports.
Read Technical Guide →
Fix vLLM ValueError: The model's max seq len is larger than the maximum number of tokens in KV cache on Linux. Tune max_model_len, FP8 KV cache, and VRAM sizing.
Read Technical Guide →
Resolve RuntimeError: This event loop is already running and Event loop is closed in Python AI agents on Linux. Clean patterns for async tool calls and threads.
Read Technical Guide →
Resolve torch._dynamo.exc.BackendCompilerFailed and CppCompileError in PyTorch 2.x on Linux. Clear Inductor caches, install Ninja, and handle dynamic shapes.
Read Technical Guide →
Architectural comparison of Instructor, BAML, and Outlines for LLM structured outputs: Pydantic validation retries, Rust schema-aligned parsing, and FSM logit masking.
Read Technical Guide →
Source-checked Cline, Roo Code and Continue architectural comparison, including approval controls, local model roles and realistic API-cost assumptions.
Read Technical Guide →
Resolve DataLoader worker killed by signal Bus error in PyTorch on Linux and Docker. Expand /dev/shm, configure file_system IPC sharing strategy, and fix worker leaks.
Read Technical Guide →
Fix Hugging Face Hub download timeouts on Linux with the current hf CLI, hf-xet transport, timeout settings, and safe restart steps for interrupted model downloads.
Read Technical Guide →
Diagnose NVML driver and library mismatches on Linux, plan a safe reboot, and understand when a controlled no-reboot module reload is possible.
Read Technical Guide →
Compare SearXNG, Tavily and Brave Search with an offline JSON response analyzer, tested fixtures, rate-limit cautions and documented API credit models.
Read Technical Guide →
Resolve RuntimeError: cuDNN error: CUDNN_STATUS_NOT_INITIALIZED and INTERNAL_ERROR in PyTorch on Linux. Fix library path conflicts and workspace OOMs.
Read Technical Guide →
Resolve FlashInfer JIT compilation failed, nvcc fatal unsupported gpu architecture, and CUDA mismatch errors in SGLang on Ubuntu Linux.
Read Technical Guide →
Resolve RuntimeError: CUDA error: device-side assert triggered in PyTorch on Linux. Step-by-step guide to unmask silent crashes and fix out-of-bounds indexing.
Read Technical Guide →
Fix RuntimeError: Expected all tensors to be on the same device in PyTorch and vLLM multi-GPU serving. Diagnose rank mismatches and device placement bugs.
Read Technical Guide →
Resolve RuntimeError: Engine core disconnected, ZMQ socket hangs, and silent AsyncLLMEngine deadlocks in production vLLM deployments on Linux.
Read Technical Guide →
Eliminate HTTP 504 Gateway Timeouts, Cloudflare Error 524, and Server-Sent Event (SSE) token buffering when serving vLLM, Ollama, and FastAPI on Linux.
Read Technical Guide →
Diagnose missing CUDA development headers in Triton, PyTorch and vLLM without guessing toolkit paths or deleting compiler caches blindly.
Read Technical Guide →
Diagnose multi-GPU vLLM NCCL failures using topology, socket, shared-memory and watchdog evidence before changing transport flags.
Read Technical Guide →
Compare LanceDB, sqlite-vec and Chroma using pinned, locally tested retrieval examples, SQLite transaction checks and clear embedding and concurrency constraints.
Read Technical Guide →
Diagnose vLLM CUDA illegal memory access on Linux with isolated reproduction, version checks, and safe worker recovery without host-wide GPU resets.
Read Technical Guide →
Fix silent Ray worker SIGKILL crashes and /dev/shm memory exhaustion in multi-GPU vLLM tensor-parallel serving with exact sysctl, PyTorch, and Docker configs.
Read Technical Guide →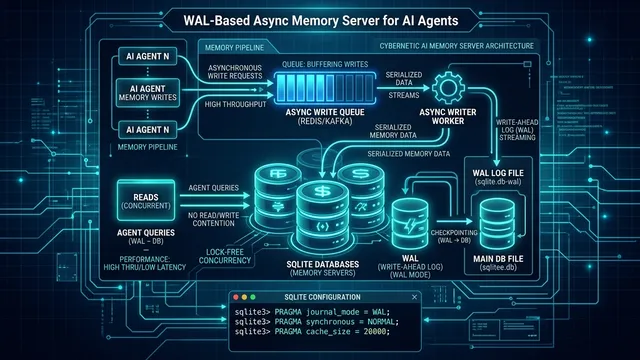
Eliminate sqlite3.OperationalError: database is locked in concurrent AI agent MCP servers. Configure WAL mode, busy timeouts, and async write-buffer queues on Linux.
Read Technical Guide →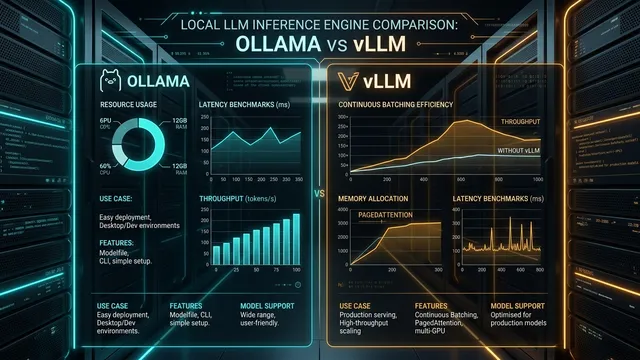
Compare Ollama and vLLM for local AI agents using official Linux configuration, KV cache behavior, safe serving examples and reproducible concurrency checks.
Read Technical Guide →
Guide to securing remote Model Context Protocol (MCP) servers under the late 2026 stateless spec. Implement bearer authentication and agentjacking defense.
Read Technical Guide →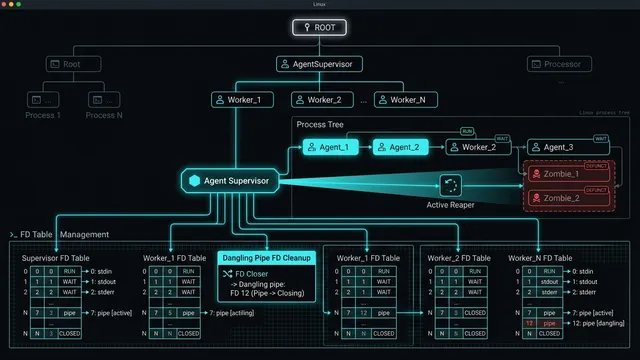
Eliminate defunct zombie processes and Errno 24 EMFILE pipe exhaustion in autonomous AI agents. Includes prctl subreaper patterns, dumb-init, and leak audits.
Read Technical Guide →
Explain SGLang RadixAttention shared-prefix reuse, current Linux installation and cache-hit measurements without unsupported TTFT speedup claims.
Read Technical Guide →
Diagnose vLLM V1 KV-cache preemption, scheduler contention and recomputation using official metrics and controlled concurrency tests.
Read Technical Guide →
Build a headless browser Model Context Protocol (MCP) server in Python with Playwright to render JavaScript SPAs and extract clean Markdown text.
Read Technical Guide →
Architectural comparison of Cursor Agent, Claude Code, and Windsurf Cascade for multi-file refactoring across AST dependency resolution, caching, and CLI execution.
Read Technical Guide →
Diagnose FlashAttention-2 wheels, PyTorch CUDA ABI mismatches, Ninja host-memory OOM and kernel import failures safely on Linux.
Read Technical Guide →
Diagnose MCP tool timeout and subprocess pipe deadlocks with safe async process handling, bounded output, and a reproducible offline test.
Read Technical Guide →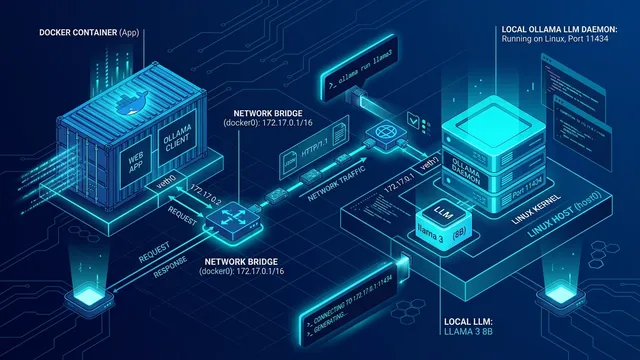
Fix Ollama connection refused from Docker on Linux with safer networking options, host-gateway diagnostics, and clear firewall exposure boundaries.
Read Technical Guide →
Build a local sqlite-vec MCP memory store using documented FastMCP APIs, check data privacy, and reproduce vector-search persistence with an offline test.
Read Technical Guide →
Set up draft-model speculative decoding in vLLM, check VRAM and tokenizer compatibility, and benchmark inter-token latency without assuming a fixed speedup.
Read Technical Guide →
Diagnose vLLM V1 GPU OOM by separating model weights, KV-cache capacity, CUDA graphs and concurrency with supported CLI flags.
Read Technical Guide →
Review Bubblewrap sandbox boundaries for AI coding agents, including writable aliases, Unix sockets, network namespaces, and host-specific risks.
Read Technical Guide →
Fine-tune DeepSeek R1 8B and 14B reasoning models locally using Unsloth and QLoRA on a single GPU. Preserves think tags and exports directly to GGUF.
Read Technical Guide →
Resolve torch.cuda.OutOfMemoryError on Linux. Configure expandable_segments, tune PyTorch memory allocator, enable FSDP, and prevent VRAM fragmentation.
Read Technical Guide →
Prevent repeating AI-agent tool calls with tested host-side budgets, failure checks, timeouts, and safe escalation instead of prompt-only safeguards.
Read Technical Guide →
Architectural comparison of 2026 open-source AI agent frameworks: LangGraph, CrewAI, AutoGen 0.4, Smolagents, and LlamaIndex Workflows across state and token overhead.
Read Technical Guide →
Production-ready .cursorrules and system prompts for Cursor, Windsurf, and AI coding agents. Includes modular rules for TypeScript, Python, and Git.
Read Technical Guide →
Resolve 'could not select device driver with capabilities: [[gpu]]' error in Docker. Complete guide to NVIDIA Container Toolkit setup on Ubuntu/Debian.
Read Technical Guide →
Check Ollama's effective context length, tune num_ctx for coding agents, and verify VRAM usage with current Modelfile, API, and Continue settings.
Read Technical Guide →
Troubleshoot and fix Model Context Protocol (MCP) exit code 1, unexpected EOF, and unbuffered stdout errors in Claude Desktop and Cursor.
Read Technical Guide →
Diagnose Docker exit code 137 versus a confirmed OOM kill using read-only Docker state and cgroup v2 checks, with a tested offline classifier.
Read Technical Guide →
Run DeepSeek R1 locally on Linux with Ollama. Updated VRAM sizing matrix (1.5B to 70B), Flash Attention flags, 32k context fixes, and IDE API setups.
Read Technical Guide →
Deploy Qwen3.8-27B with documented BF16, INT4, FP8, and NVFP4 checkpoints. Check Linux GPU memory, vLLM parsers, and reproducible startup steps.
Read Technical Guide →
Build a read-only Model Context Protocol (MCP) server in Python to let AI coding agents inspect schemas and query PostgreSQL and SQLite databases.
Read Technical Guide →
Build a small read-only MCP server using the official Python SDK v2, with a tested STDIO client handshake and clear configuration and security boundaries.
Read Technical Guide →